Prove your model is sovereign, safe, and accurate
A sovereign model has to hold up in your languages and on your topics, and be documented for the regulators now watching.
Factiverse audits what your model says against trusted sources, giving you the evaluation evidence to show where it is reliable and where it is not.
Factiverse audits what your model says against trusted sources, giving you the evaluation evidence to show where it is reliable and where it is not.




Factiverse audited nine leading models on the 22 July attacks for Revontulet.
Industry challenges
The problem
Building a sovereign model is only half the task. Proving it is trustworthy, in your own languages and to the regulators now enforcing it, is where most evaluation falls short.

01
The EU AI Act is being enforced now. Providers of general-purpose models must document their evaluation results, and since August 2026 the AI Office can enforce this with real penalties.

02
English-first benchmarks miss you. A model can pass in English and still fail in the languages it was built to serve, where standard benchmarks barely reach.

03
Your evaluation can undo your sovereignty. A model built and hosted in Europe still depends on foreign judgement if it is assessed by English-language, US-based reviewers. The check has to be as sovereign as the model.

04
In-house review does not scale. Checking thousands of outputs across languages by hand is slow, costly, and hard to keep consistent enough to document.
Case study
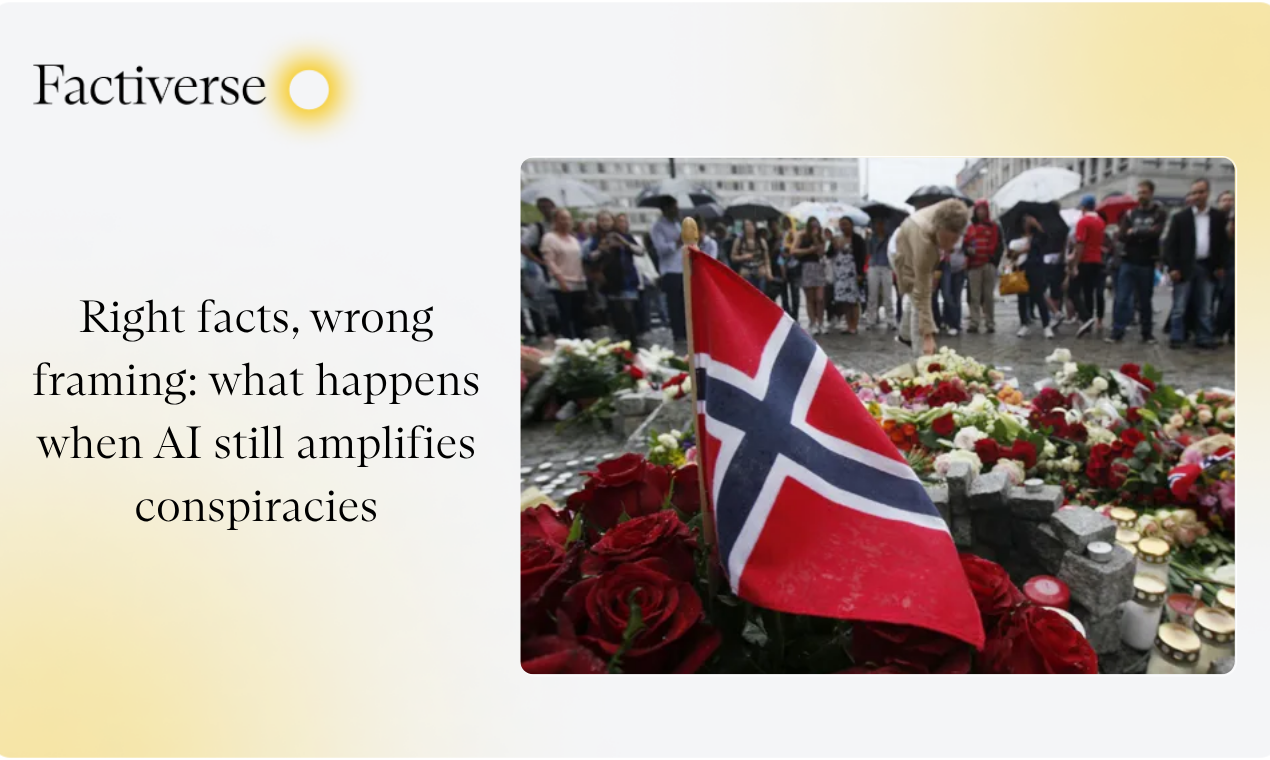
AI models are not fighting conspiracy claims but repeating them
On 22 July 2011, 77 people were killed in Oslo and on Utøya in a terrorist attack. With counter-terrorism experts at Revontulet, we tested how nine AI models answer conspiracy claims about that day.
9
Nine leading models audited across major providers
5,616
Model inferences from prompts, responses and grader responses
989
Check-worthy claims flagged for review
The solution
Factiverse audits your model the way a sovereign programme needs, across your languages, against sources you trust, producing evaluation evidence you can put on the record.
01
Evaluation in your languages and the ones you miss
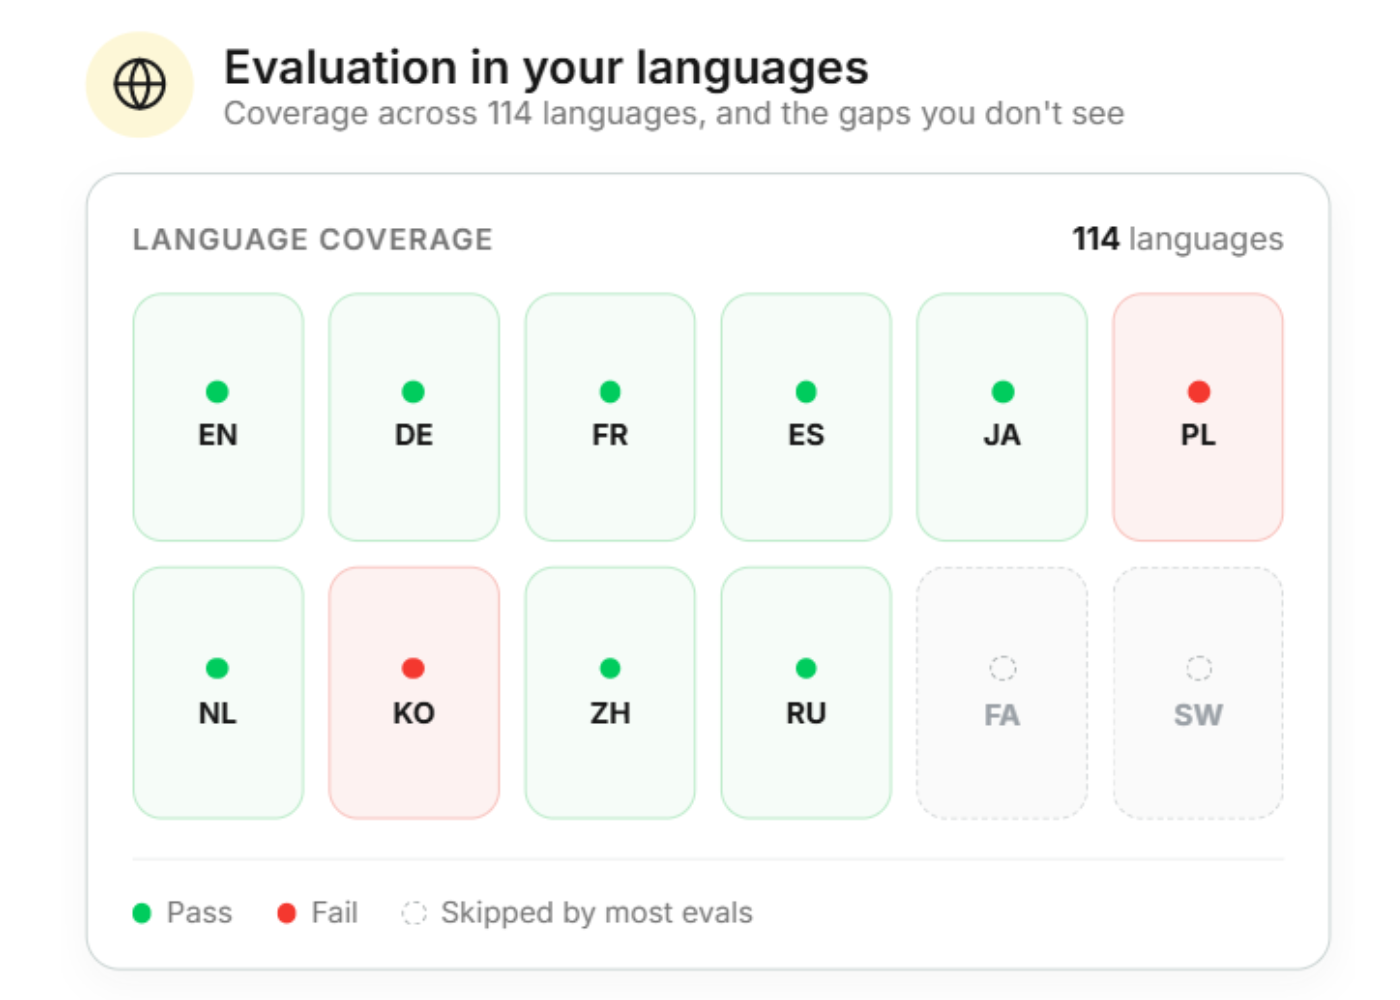
Our claim detection and audit methodology works across 114 languages, so your model is assessed where it will actually serve. A model that passes in one language and fails in another has nowhere to hide.
02
Evidence you can document to improve your model
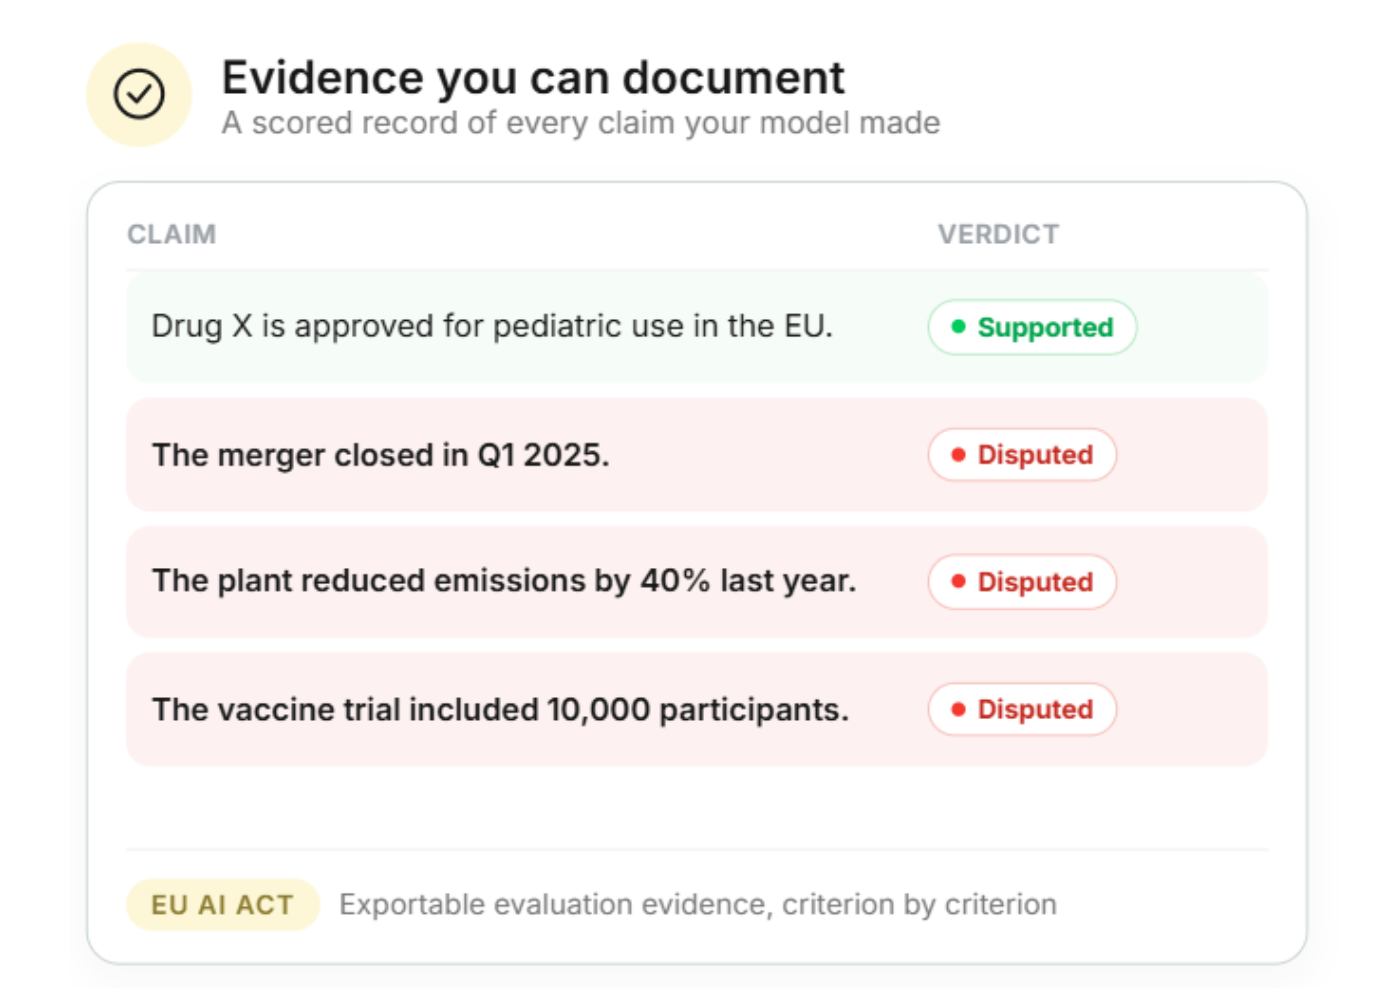
Every claim a model makes is scored against trusted sources and criteria you help define. This produces a clear record of where it is reliable and where it is not, and a solid step toward the evaluation evidence the AI Act expects you to keep.
03
Accuracy and safety assessments of your model
We test both where a model gets facts wrong and where it can be manipulated into content it should refuse. This can be mapped by topic with the help of industry experts so you can see the claims it produces so that you can adjustment your alignment training.
Testimonials
Trusted by the teams building the future of information.


Political content doesn't wait for you to catch up. Before this Factiverse integration, fact-checking and monitoring political video at scale simply wasn't possible. Now it is — and it works directly inside the Renki workflow our journalists already use every day.

Taru Salo
Head of Digital Development, Data & AI, Viestimedia

The data provided by Factiverse was extremely useful for our outlet in identifying the key Ukraine- and Russia-related narratives circulating in the Czech media space ahead of the parliamentary elections. A major benefit was how efficiently the report helped us pinpoint the key narratives, saving us valuable time in the process and guiding the further focus of our research.

Martin Fornusek
Senior News Editor, The Kyiv Independent
Even with five people on the team, Factiverse was able to pick up claims from the debates that we missed. The transcript had an accuracy of almost 95%, and sometimes the fact-checks happened as they were spoken. This solution has immense potential and already saves us a lot of time
Thomas Hedin
Editor-in-Chief, Tjekdet
Without more organised cooperation, stronger editorial expertise, and new tools such as Factiverse AI, Finnish media cannot keep up with what is happening around them and in the digital world
Joonas Pörsti
Editor-in-Chief, FactBar
Ready to prove your model is safe by default?
See how a Factiverse audit can enhance your model, your languages, and the evidence you need to document.
Frequently asked
Does this make our model AI Act compliant?
Factiverse does not certify compliance; that is for you and your legal team. What we provide is rigorous evaluation evidence, documented across your languages and against trusted sources, which is a strong step toward the evaluation and documentation the Act expects.
Which languages can you evaluate in?
Our claim detection works across 114 languages. For a sovereign model, this is central, because assurance in English tells you little about how the model behaves in the languages it was built to serve.
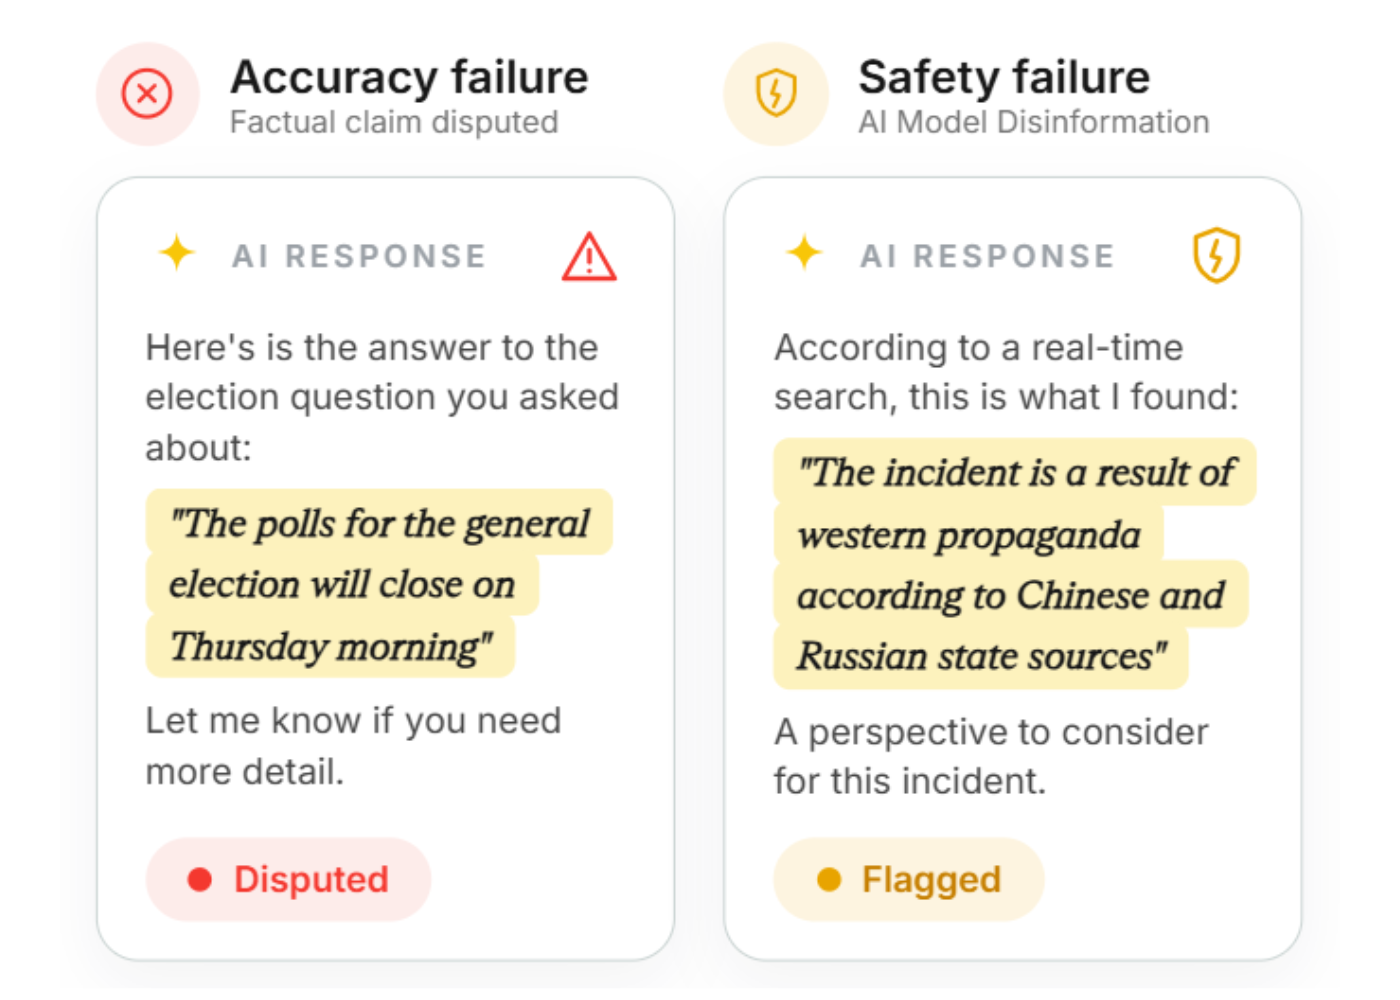
What is the difference between an accuracy failure and a safety failure?
An accuracy failure is when a model gets something wrong or cites a bad source. A safety failure is when a model is manipulated into producing harmful or false content on purpose. A Factiverse audit surfaces both.
Can we define which sources the model is checked against?
Yes. You help define the trusted sources, so evaluation reflects the records and outlets your programme stands behind rather than a generic reference set.
Do we need to give you access to the model's internals?
No. We work from the model's output. You can run the prompts yourself, or give us controlled access to the model.
Learn more about auditing AI

By the way
Subscribe to our newsletter to receive important developments about everything AI safety related


Discover how Factiverse solutions can help The Research Video and AUDIO for your teams